> For the complete documentation index, see [llms.txt](https://docs.flowiseai.com/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://docs.flowiseai.com/integrations/langchain/document-loaders/text-file.md).
# Text File
Load data from text files.
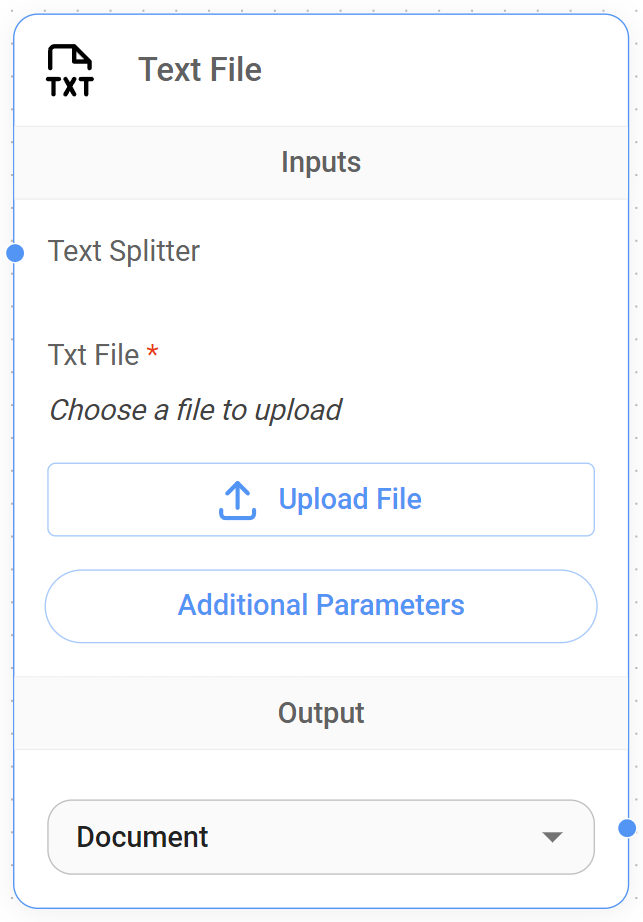
Text File Node
The Text File loader enables you to load and process content from various text-based file formats. It supports multiple file types and provides flexible options for text splitting and metadata handling.
## Features
* Support for multiple text-based file formats
* Multiple file loading capability
* Text splitting support
* Customizable metadata handling
* Storage integration support
* Base64 file handling
* Multiple output formats
## Supported File Types
The loader supports a wide range of text-based file formats:
* Text files (.txt)
* Web files (.html, .aspx, .asp, .css)
* Programming languages:
* C/C++ (.cpp, .c, .h)
* C# (.cs)
* Go (.go)
* Java (.java)
* JavaScript/TypeScript (.js, .ts)
* PHP (.php)
* Python (.py, .python)
* Ruby (.rb, .ruby)
* Rust (.rs)
* Scala (.sc, .scala)
* Solidity (.sol)
* Swift (.swift)
* Visual Basic (.vb)
* Markup/Style:
* CSS/LESS/SCSS (.css, .less, .scss)
* Markdown (.md, .markdown)
* XML (.xml)
* LaTeX (.tex, .ltx)
* Other:
* Protocol Buffers (.proto)
* SQL (.sql)
* RST (.rst)
## Inputs
### Required Parameters
* **Txt File**: One or more text files to process
* Accepts files from local upload or storage
* Supports multiple file selection
### Optional Parameters
* **Text Splitter**: A text splitter to process the extracted content
* **Additional Metadata**: JSON object with additional metadata to add to documents
* **Omit Metadata Keys**: Comma-separated list of metadata keys to exclude
* Format: `key1, key2, key3.nestedKey1`
* Use \* to remove all default metadata
## Outputs
* **Document**: Array of document objects containing:
* metadata: File metadata and custom fields
* pageContent: Extracted text content
* **Text**: Concatenated string of all extracted content
## Document Structure
Each document contains:
* **pageContent**: The main content from the text file
* **metadata**:
* Default file metadata
* Additional custom metadata (if specified)
* Filtered metadata (based on omitted keys)
## Usage Examples
### Single File Processing
```json
{
"txtFile": "example.txt",
"metadata": {
"source": "local",
"category": "documentation"
}
}
```
### Multiple Files Processing
```json
{
"txtFile": ["doc1.txt", "doc2.md", "code.py"],
"metadata": {
"batch": "docs-2024",
"processor": "text-loader"
},
"omitMetadataKeys": "source, timestamp"
}
```
## Storage Integration
The loader supports two file source modes:
1. **Direct Upload**: Files uploaded directly through the interface
2. **Storage Integration**: Files accessed through the storage system
* Format: `FILE-STORAGE::filename.txt`
* Supports organization and chatflow-specific storage
## Notes
* Handles both single and multiple file processing
* Supports base64 encoded file content
* Automatically handles different file encodings
* Memory-efficient processing of large files
* Preserves file metadata when needed
* Supports text splitting for large documents
* Handles escape characters in output text
* Integrates with organization-specific storage
{% hint style="info" %}
This section is a work in progress. We appreciate any help you can provide in completing this section. Please check our [Contribution Guide](https://github.com/FlowiseAI/FlowiseDocs/blob/main/en/integrations/langchain/document-loaders/broken-reference/README.md) to get started.
{% endhint %}
---
# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.
## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation by asking a question.
Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:
```
GET https://docs.flowiseai.com/integrations/langchain/document-loaders/text-file.md?ask=&goal=
```
`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `automate deployments from our CI pipeline` lets GitBook tailor the answer to that use case.
The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.
Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.