> For the complete documentation index, see [llms.txt](https://docs.flowiseai.com/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://docs.flowiseai.com/espanol/documentacion-oficial/integraciones/langchain/document-loaders/spider-web-scraper-crawler.md).
# Spider Web Scraper/Crawler
Haz scraping y crawling de la web con Spider - el web scraper y crawler de código abierto más rápido.
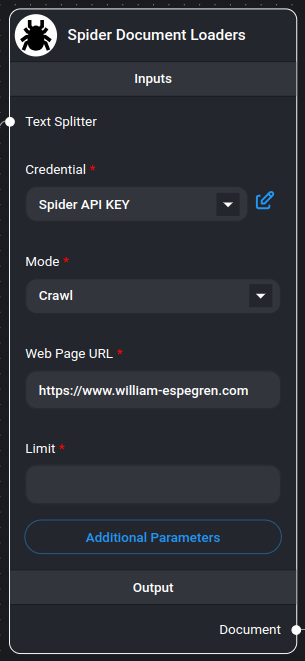
Nodo Spider Web Scraper/Crawler
[Spider](https://spider.cloud/?ref=flowise) es el web scraper y crawler de código abierto más rápido que devuelve datos preparados para LLM. Para comenzar a usar este nodo necesitas una clave API de [Spider.cloud](https://spider.cloud/?ref=flowise).
## Comenzar
1. Ve al sitio web de [Spider.cloud](https://spider.cloud/?ref=flowise) y regístrate para obtener una cuenta gratuita.
2. Luego ve a [API Keys](https://spider.cloud/api-keys) y crea una nueva clave API.
3. Copia la clave API y pégala en el campo "Credential" en el nodo Spider.
## Scraping y Crawling
1. Elige "Scrape" o "Crawl" en el menú desplegable de modo.
2. Ingresa la URL que deseas analizar o rastrear en el campo "Web Page URL".
3. Si elegiste "Crawl", ingresa la cantidad máxima de páginas que deseas rastrear en el campo "Limit". Si no se ingresa ningún valor o se ingresa 0, el crawler rastreará todas las páginas.
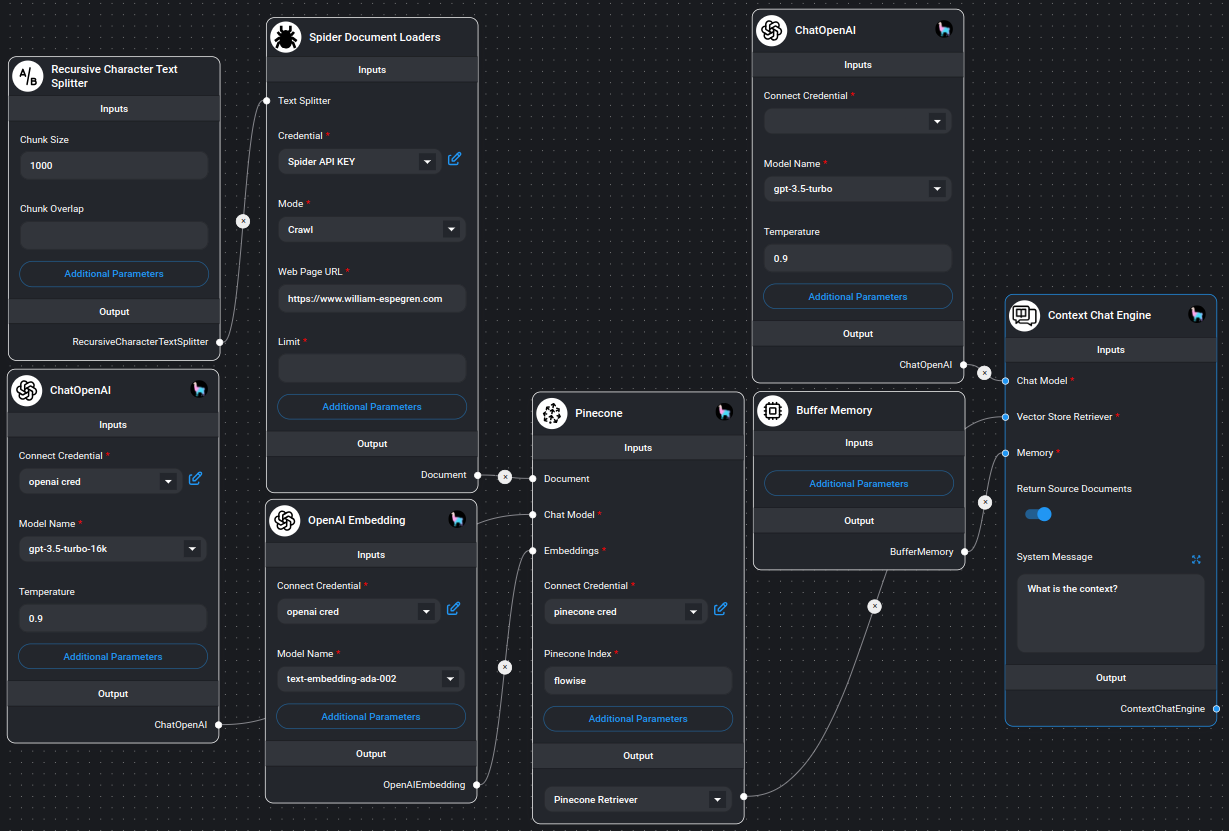
## Ejemplo
Ejemplo de uso del nodo Spider
---
# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.
## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation by asking a question.
Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:
```
GET https://docs.flowiseai.com/espanol/documentacion-oficial/integraciones/langchain/document-loaders/spider-web-scraper-crawler.md?ask=&goal=
```
`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `automate deployments from our CI pipeline` lets GitBook tailor the answer to that use case.
The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.
Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.